Reviews AI Models
Qwen4-Max Review: MoE Architecture, 1M Context Pricing and API Capabilities
At a glance
Alibaba released Qwen4-Max on November 16, 2026, a 2.4T-parameter sparse MoE model with native multimodal input and a 1M-token context window available through its cloud API.
Qwen4-Max is Alibaba’s flagship proprietary multimodal model released on November 16, 2026. The sparse MoE architecture uses a 2.4T-parameter backbone with 71B active parameters per token and adds 328B N-gram embedding parameters for local pattern handling. It processes text, image, and video inputs while generating text outputs.
The model runs exclusively on QwenCloud and related Alibaba platforms. No open weights are available for the Max variant, though smaller open Qwen4 models are planned for later release.
Qwen4-Max Architecture and API Capabilities
Qwen4 introduces several architectural changes aimed at efficiency and long-context stability. Gated DeltaNet combined with Qwen Sparse Attention operates at a 3:1 layer ratio and uses micro-block indexing. A Gated Residual structure runs four parallel branches with dynamic gates, while N-gram embeddings improve handling of repeated local sequences. Training completed without reported loss spikes.
The context window reaches 1M tokens. Maximum input length is listed at approximately 991.8K tokens without thinking mode or 983.6K tokens with thinking enabled. Output can extend to 131K tokens in standard mode or up to 262K tokens when combining thinking and final answer. Reasoning runs at high effort by default, with low, high, xhigh, or off options available.
API features include tool calling with parallel execution, structured JSON Schema output, web search integration, streaming responses, prefix completion, and both explicit and implicit caching. The interface maintains compatibility with OpenAI and Anthropic formats in addition to DashScope. Batch inference, fine-tuning, and self-hosting remain unavailable.
Qwen4-Max Pricing and Performance Data
International list pricing stands at $1.50 per million input tokens and $4.50 per million output tokens as of November 17, 2026. Cached reads cost $0.075 per million tokens. Explicit cache writes carry higher rates, such as $1.875 for a five-minute window. Some regions list slightly lower figures around $1.413 input and $4.24 output.
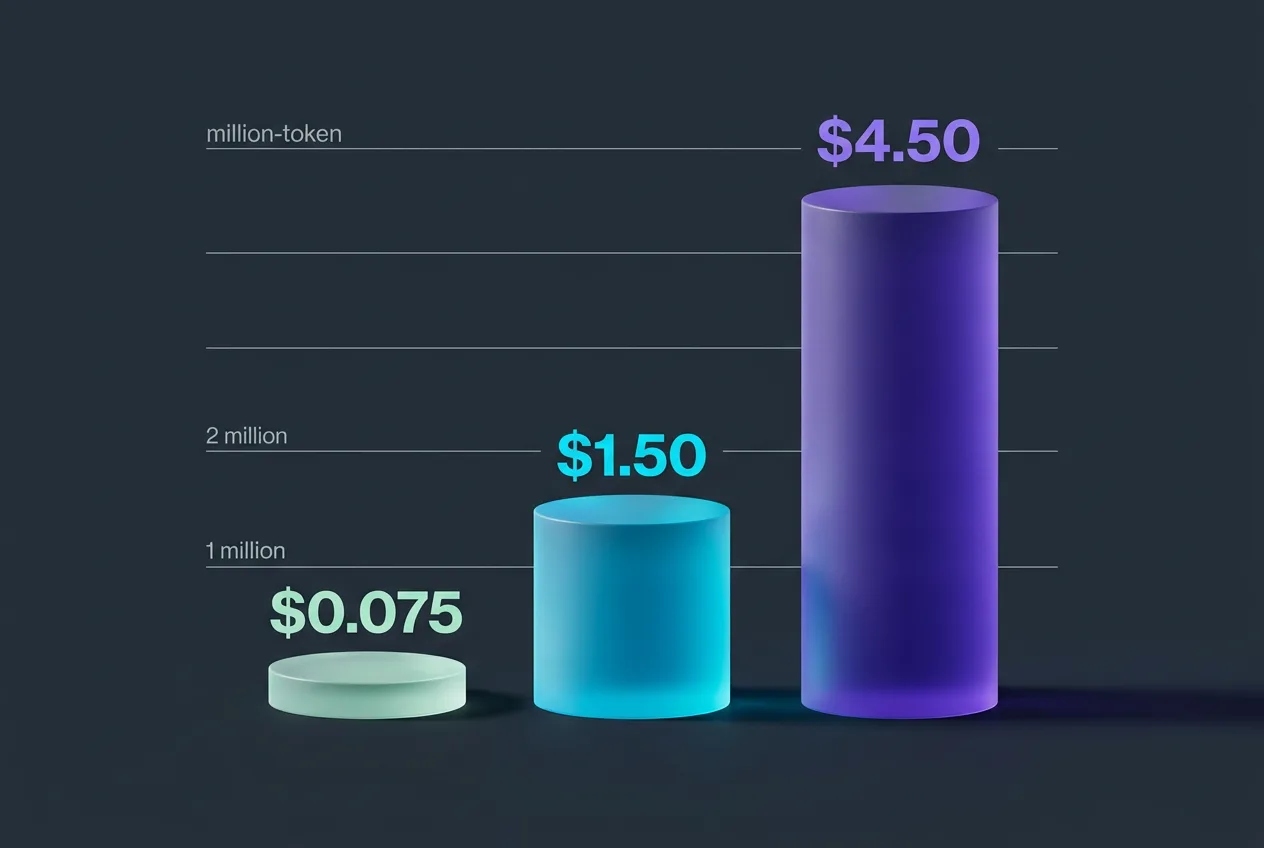
Alibaba states the model delivers roughly 62 percent lower average cost per task on its internal Work360 benchmark compared with the prior generation. Savings come from the reduced per-token rates, 25–35 percent fewer tokens consumed on equivalent work, and heavy use of caching.
Independent benchmarks place Qwen4-Max at 63.20 percent on the Vals Index, ranking 11th among 38 models evaluated. The Artificial Analysis Intelligence Index scores it at 43, nine points above Qwen3.8-Max yet three points behind Kimi K3.1 Pro. Stronger results appear on agentic, legal, and finance tasks, while performance trails certain U.S. models on terminal coding, chart interpretation, and complex video reasoning.
| Model | Input Price (per 1M) | Output Price (per 1M) | Context Window | Intelligence Index |
|---|---|---|---|---|
| Qwen4-Max | $1.50 | $4.50 | 1M | 43 |
| Kimi K3.1 Pro | — | — | 1M | 46 |
| Qwen3.8-Max | $2.00 | $6.00 | — | 34 |
Limitations and Current Standing
Access remains restricted to hosted API endpoints with no self-hosting path. Certain workloads, particularly long video sequences or intricate coding tasks, show variance between vendor and independent test results. Users should run direct evaluations on target use cases before committing to production volumes.
Public user reviews and complaint data are still limited because the model reached general availability only one day prior to this review. Early reports focus on cost reductions and context handling rather than widespread reliability issues.
Frequently asked questions
What is the context window size of Qwen4-Max?
The model supports a 1M-token context window. Maximum input reaches roughly 991K tokens without thinking mode and 983K tokens with thinking enabled.
How much does Qwen4-Max cost per million tokens?
List pricing is $1.50 for input and $4.50 for output tokens. Cached reads drop to $0.075 per million tokens.
Does Qwen4-Max support tool calling and structured output?
Yes. The API includes parallel tool calling, JSON Schema structured output, web search, streaming, and prefix completion.
Is Qwen4-Max available for self-hosting or fine-tuning?
No. The model is accessible only through Alibaba’s hosted API platforms. Fine-tuning and self-hosting options are not offered.
Filed under
Comments 8