Reviews OpenAI
GPT-6.2 Astra Review: OpenAI Model Capabilities and Enterprise Use
At a glance
GPT-6.2 Astra provides a 1.05 million token context window and agentic capabilities for professional tasks. This review covers its pricing, benchmarks, and enterprise constraints.
GPT-6.2 Astra launched on November 17, 2026, as OpenAI's frontier model for complex professional and agentic workflows in science, law, finance, and coding. It accepts text and image inputs while producing text outputs that follow templates more closely than prior versions. The model emphasizes fewer output tokens and cleaner results for document, slide, and spreadsheet generation.
GPT-6.2 Astra Review: Capabilities, Context Window, and Benchmarks
The model supports a 1,050,000-token context window, with maximums of roughly 922,000 input tokens and 128,000 output tokens. Knowledge cutoffs stand at May 18, 2026, for Astra. Users can select reasoning effort levels from low to max, and the system includes function calling, structured outputs, and tools such as web search, code interpreter, and computer use. OpenAI reports new highs on Agents’ Last Exam with a 5.2-point gain over GPT-6 Astra at under one-third the cost, plus a 9-point increase on Terminal-Bench-Science 0.1 and a 6.2-point rise on GDPval v2 with 22 percent fewer output tokens.
Independent evaluations place Astra at 62 on the Artificial Analysis Intelligence Index, second to Claude Fable 5.2 at 65. On the Epoch Capabilities Index, Astra scores 174, tied with Fable 5.2. Early external tests confirm task-cost reductions between 36 and 50 percent, though gains vary by workload. Sol, the companion model, delivers near-Astra coding performance at roughly one-fifth the price.
API Pricing, Enterprise Limits, Safety, and Comparisons
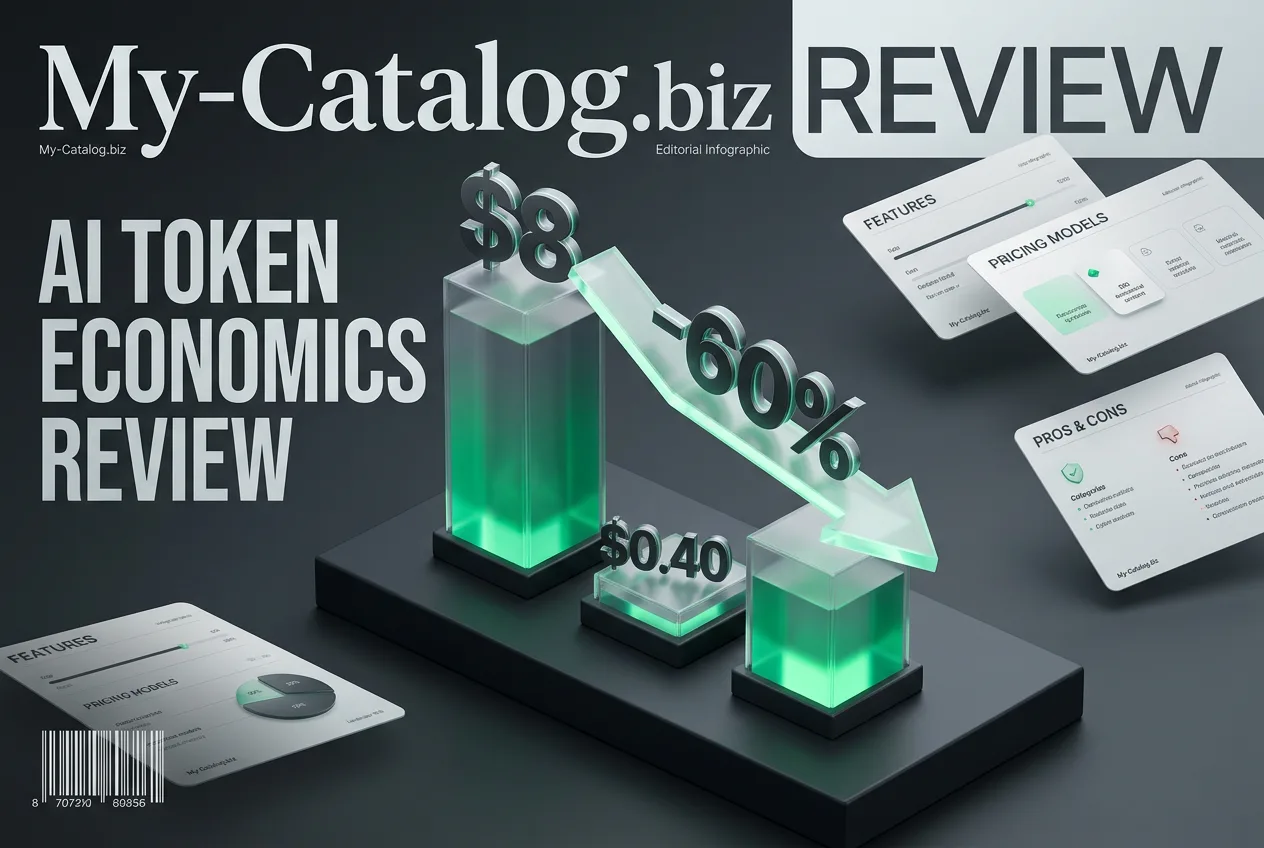
Standard pricing for Astra lists $8 per million input tokens, $0.40 for cached input, and $40 for output, representing a 20 percent drop from GPT-6 Astra and a 60 percent reduction on cached tokens. Sol costs $2 input, $0.10 cached, and $10 output. Batch API runs at 50 percent of standard rates. Fast and ultrafast tiers multiply costs by two or three through February 28, 2027, then six times for ultrafast. Long-context inputs above 272,000 tokens incur roughly double input and cache fees plus 1.5 times output charges. Cache writes for Astra run $10 with 30-minute retention.
Rate limits scale by tier: Build offers 5,000 RPM and 1 million TPM, Launch 10,000 RPM and 4 million TPM, and Grow 15,000 RPM and 40 million TPM. ChatGPT Work and Codex plans provide 5 to 45 local Astra messages per five-hour window on lower tiers, with higher allowances and no time caps on Pro plans. Enterprise accounts face virtually unlimited base-model access subject to spend caps and anti-abuse rules, though Astra often remains disabled by default.
Both models meet OpenAI’s Critical threshold for cybersecurity and High for biological or chemical risks. Astra becomes the first externally released model to reach High for AI self-improvement. Default safeguards tighten on high-risk cyber tasks, and the system card notes improved alignment alongside reduced chain-of-thought monitorability. No major safety incidents have surfaced since launch.
| Model | Input Price (per 1M) | Output Price (per 1M) | Context Window | Key Strength |
|---|---|---|---|---|
| GPT-6.2 Astra | $8 | $40 | 1.05M | Agentic professional tasks |
| Claude Fable 5.2 | Undisclosed | Undisclosed | 1M | Intelligence index lead |
| GPT-6.1 Sol | $2 | $10 | 1.05M | Everyday efficiency |
Compared with Claude Fable 5.2, Astra trails slightly on the Artificial Analysis index but undercuts cost on several agent benchmarks. Against GPT-6 Astra, it delivers measurable efficiency gains at lower token prices. Limitations include tiered rate limits that constrain high-volume use outside Enterprise agreements and decreased monitorability of reasoning steps in some evaluations.
Frequently asked questions
What is the context window size for GPT-6.2 Astra?
GPT-6.2 Astra supports a 1,050,000-token context window with up to 922,000 input tokens and 128,000 output tokens.
How does GPT-6.2 Astra pricing compare to GPT-6 Astra?
Input costs drop 20 percent to $8 per million tokens and cached input falls 60 percent to $0.40, while output remains at $40 per million tokens.
What rate limits apply to GPT-6.2 Astra in the API?
Limits vary by tier, starting at 5,000 requests per minute and 1 million tokens per minute on the Build plan and scaling higher on Launch and Grow tiers.
Does GPT-6.2 Astra meet OpenAI safety thresholds?
It reaches Critical for cybersecurity and High for biological, chemical, and AI self-improvement capabilities under the Preparedness Framework.
Filed under
Comments 1