Reviews AI Models
TwIL-8B Review: webAI’s 8.8B Reasoning Model MATH-500 Performance and Non-Commercial License Details
At a glance
TwIL-8B delivers 98.2 on MATH-500 with an 8.79B parameter model under a non-commercial license. This review examines its architecture, benchmarks, and practical constraints.
TwIL-8B is an 8.79 billion parameter decoder-only model released by webAI on November 4, 2026. It posts a self-reported 98.2 score on MATH-500 and runs quantized versions on roughly 5 GiB of memory. The model targets math, code, and instruction tasks while remaining restricted to non-commercial use.
Model Architecture and Key Capabilities
webAI built TwIL-8B on IBM Granite 4.2 8B using full-parameter supervised fine-tuning on reasoning traces followed by GRPO and length-aware reinforcement learning. The architecture uses 40 layers, a 4096 hidden size, and 32 attention heads with 8 KV heads. It emits explicit blocks and supports 131k context with a 100k+ vocabulary tokenizer limited to English input and output.
Two variants exist: a balanced version that produces shorter traces and a verbose version for harder problems. Both ship in bf16 at 16.38 GiB, Q4_K_M GGUF at 4.98 GiB, and Q8_0 at 8.70 GiB. No hosted inference endpoint is available on Hugging Face as of the release date.
Users can run the quantized forms on consumer hardware such as a 64 GB Mac or modest GPUs via llama.cpp. The model applies 13-gram decontamination against common benchmarks and focuses on cost-per-task rather than parameter count.
MATH-500 Results and Competitor Comparison
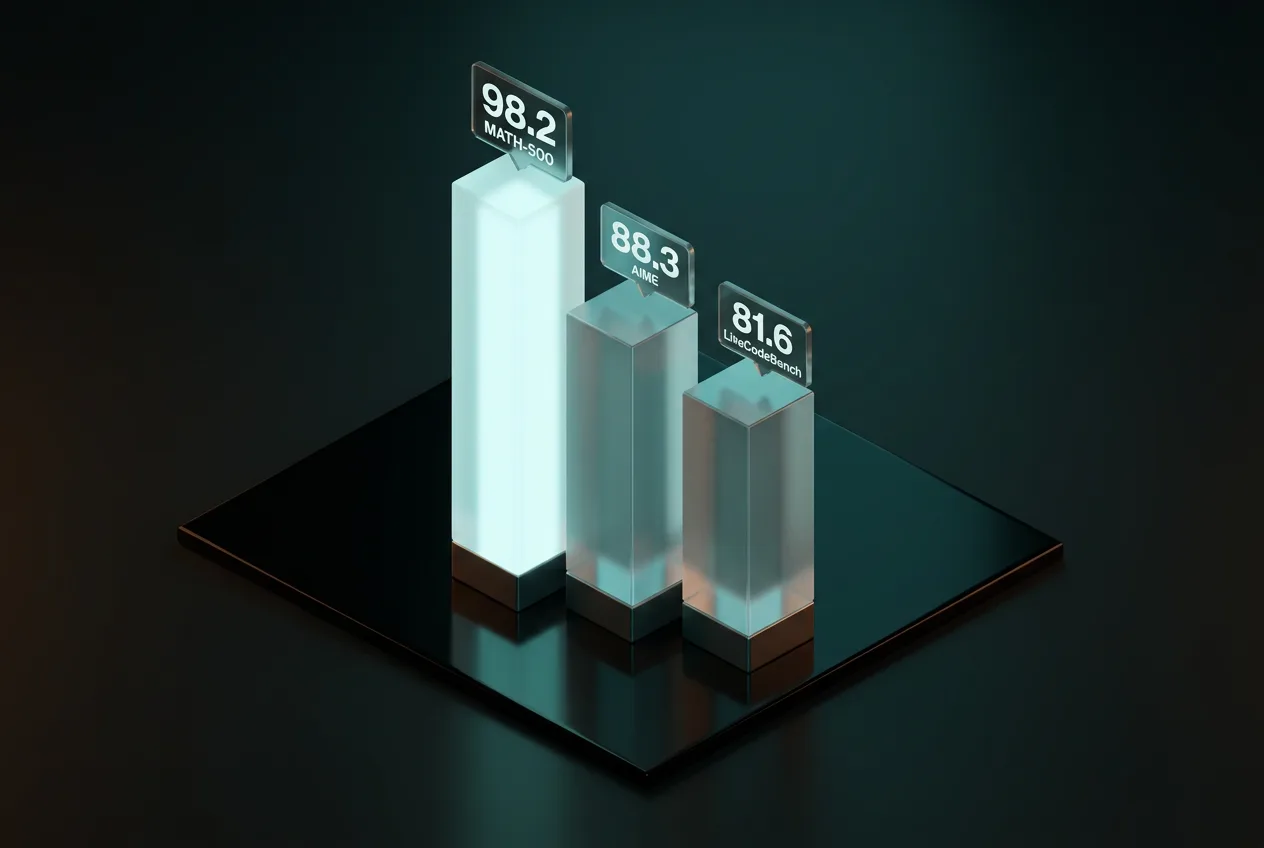
webAI reports 98.2 on MATH-500 for the balanced variant, 81.6 on LiveCodeBench for the verbose variant, and 88.3 on both AIME 2025 and AIME 2026. It records 70.2 on GPQA Diamond and 76.5 on MMLU-Pro, trailing larger models on knowledge-heavy tasks. Across 13 shared benchmarks it wins seven and loses six against Qwen3.5-9B while trailing Gemma 4 31B on eleven of thirteen.
| Benchmark | TwIL-8B | Qwen3.5-9B | Gemma 4 31B |
|---|---|---|---|
| MATH-500 | 98.2 | 96.6 | 87.9 |
| LiveCodeBench | 81.6 | 65.6 | 80.0 |
| AIME 2026 | 88.3 | 92.5 | 89.2 |
| GPQA Diamond | 70.2 | 81.7 | 84.3 |
| MMLU-Pro | 76.5 | 82.5 | — |
The model uses an average of 19.5k output tokens on AIME 2026 problems, 38 percent fewer than Qwen3.5-9B at comparable accuracy. This efficiency holds across other contest benchmarks and supports the emphasis on local deployment rather than scale.
License Terms, Access, and Reported Limitations
Weights are distributed under the webAI Non-Commercial License version 1.0, which permits research, education, and personal use only. The base Granite weights remain under Apache 2.0, but the fine-tuned TwIL-8B weights carry the stricter restriction. No commercial deployment rights are granted at release.
Benchmark numbers come solely from webAI self-reporting; independent third-party leaderboards have not yet appeared. Exact LiveCodeBench version details and full quantization accuracy loss remain unverified. User reports on social platforms mention strong performance on small custom tests, yet these remain anecdotal and unscalable at present.
webAI indicated possible updates to access terms around November 5–6, 2026. Until then, the model suits local math and code workflows where non-commercial terms align with the intended use case.
Frequently asked questions
What license applies to TwIL-8B weights?
The model uses webAI Non-Commercial License version 1.0. Users may employ it for research, education, and personal projects but not for commercial products or services.
How large are the quantized TwIL-8B files?
Q4_K_M GGUF files measure approximately 4.98 GiB. This size allows running on CPUs or GPUs with modest VRAM using llama.cpp.
Does TwIL-8B require hosted inference?
No hosted endpoint exists on Hugging Face. Users must download and run the model locally with compatible inference engines.
How does TwIL-8B compare to Qwen3.5-9B on math tasks?
It scores 98.2 versus 96.6 on MATH-500 while using fewer output tokens on average. It wins seven of thirteen shared benchmarks against that model.
Filed under
Comments
No comments yet. Be the first!