Reviews AI Models
Ripple-65B Preview Review: Ricursive Intelligence’s 65B Dense Open-Weight Model Benchmarks and Context Limits
At a glance
Ripple-65B Preview is Ricursive Intelligence’s first open-weight 65B dense model, released November 4 2026, with strong agentic coding scores and official 1M-token context.
Ripple-65B review starts with the model’s core specifications. Ricursive Intelligence released the 65B-parameter dense Transformer on November 4 2026 as its first open-weight model. The Palo Alto lab pretrained it from scratch on 12 trillion tokens, primarily English text and code, and supports up to 1M-token context through staged long-context training.
The architecture uses 80 layers and a d_model of 5120. It incorporates gated attention, global NoPE, value residuals, FFN activation clipping, and a mix of sliding-window plus global attention. Post-training consisted of 1.4 million RL rollouts focused on agentic coding tasks. The company reports total R&D cost at $32 million.
Ripple-65B review: Benchmarks, Context Handling, and Pricing
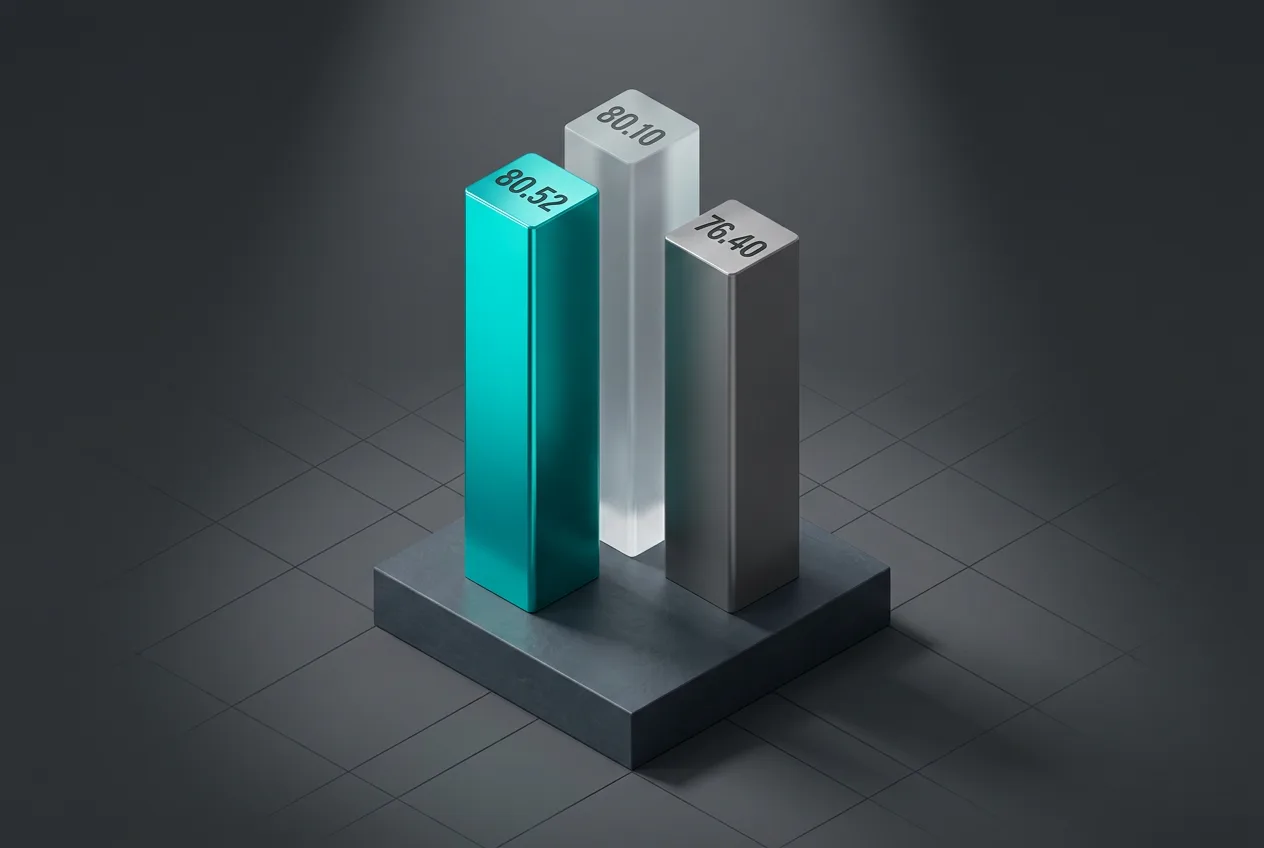
Self-reported results place Ripple-65B at 80.52 on Terminal-Bench 2.1, ahead of Reflection Beam 501B at 80.1 and Meta Muse Spark Open 816B at 76.4. On SWE-bench Pro v2.0 Hard the score reaches 79.1. Performance trails on SWE-bench Verified (76.5 versus 81.6 for Beam) and on SciCode (39.4). In Ricursive’s Terminus 2 harness rerun at 128K context the model maintained 80.5 while some competitors declined.
Official context length is 1M tokens. Hosted endpoints on Together AI, GMI Cloud, and OpenRouter quote roughly $0.20 per million input tokens and $0.60 per million output tokens. Effective context on some platforms starts at 16K before scaling to full length. Inference speed reaches approximately 250 tokens per second on two B200 GPUs in BF16 precision. An experimental NVFP4 checkpoint targets local NVIDIA DGX Spark hardware.
Weights are released under Apache 2.0 on the ricursiveAI Hugging Face organization. Checkpoints include BF16 instruct, BF16 base, NVFP4, and a DFlash2 drafter. The dense design was chosen over mixture-of-experts for lower complexity and better hardware efficiency during both training and inference.
Comparisons, Limitations, and Assessment
Compared with other recent open-weight models, Ripple-65B leads on Terminal-Bench 2.1 yet trails larger models on several knowledge and math benchmarks. Its 65B size offers lower inference cost than 500B-plus competitors while delivering competitive agentic coding results. API pricing sits between typical 70B and 405B offerings on the same providers.
Limitations include the absence of widespread independent verification as of November 5 2026. Several benchmarks remain self-reported only. Context-window performance beyond 128K has not been confirmed by third parties, and some hosted endpoints initially cap context far below the advertised 1M tokens. Community fine-tuning and harness reconciliation are still pending.
Ripple-65B Preview provides a publicly available 65B dense model with documented strength in agentic coding and long context. Its release supplies researchers and developers with weights, multiple quantization options, and early API access while leaving room for external validation of the reported scores.
Frequently asked questions
What is the context length of Ripple-65B Preview?
Official support reaches 1M tokens after staged pretraining that began at 8K sequences and included 2M-token long-context stages. Some hosted endpoints initially limit context to 16K before full rollout.
How does Ripple-65B score on Terminal-Bench 2.1?
Ricursive reports 80.52, placing it ahead of Reflection Beam 501B at 80.1. Independent confirmation remains limited as of the November 4 2026 release.
What license covers the Ripple-65B weights?
The model is released under Apache 2.0. Weights and checkpoints are available on the ricursiveAI organization page on Hugging Face.
What is the inference speed of Ripple-65B on B200 GPUs?
The model reaches roughly 250 tokens per second on two B200 GPUs in BF16 precision according to provider documentation.
Filed under
Comments 1