Reviews AI Models
Claude Fable 5.2 Review: 1M Context Window and Agentic Work Capabilities
At a glance
Anthropic released Claude Fable 5.2 on November 9, 2026, with a 1M-token context window and strong results on long-horizon coding and research tasks.
Claude Fable 5.2 is Anthropic’s latest generally available model for complex agentic technical work. Launched November 9, 2026, it targets coding, multi-step research, and analysis projects that run over extended periods. The model carries a 1M-token context window and supports up to 128K output tokens.
Claude Fable 5.2 Features, Performance, and Access
Key specifications include an always-on adaptive thinking mode controlled by an effort parameter, with the default set to high on API calls. Knowledge cutoff stands at June 2026. The model ID is claude-fable-5-2 and it is reachable through the Claude Platform, AWS Bedrock, Google Cloud, and Microsoft Foundry. On paid plans the model appears in the picker for web, mobile, and desktop apps.
Anthropic benchmarks show Fable 5.2 reaching 49.1 percent on FrontierCode 2.0 agentic coding, 69.9 percent on FrontierSWE v2, and 89.3 percent on OSWorld 2.1 computer use. It outperforms Opus 5.5 on most listed rows while matching some best scores at roughly half the cost per task when effort settings are optimized. Pre-release demonstrations included coordinating one thousand agents to formalize a Fermat’s Last Theorem proof in thirty hours and completing a full operating system build over eight days.
Access requires a paid Claude plan; the free tier is excluded. A launch promotion through November 16, 2026, Pacific Time, includes Fable 5.2 up to fifty percent of weekly limits on eligible plans. All accounts face a mandatory thirty-day data retention period unless zero-DR authorization is granted. Mythos 5.2, the same base model with fewer safeguards, remains limited to verified organizations through specific Cyber and Life Sciences programs.
Claude Fable 5.2 Pricing, Comparisons, and Limitations
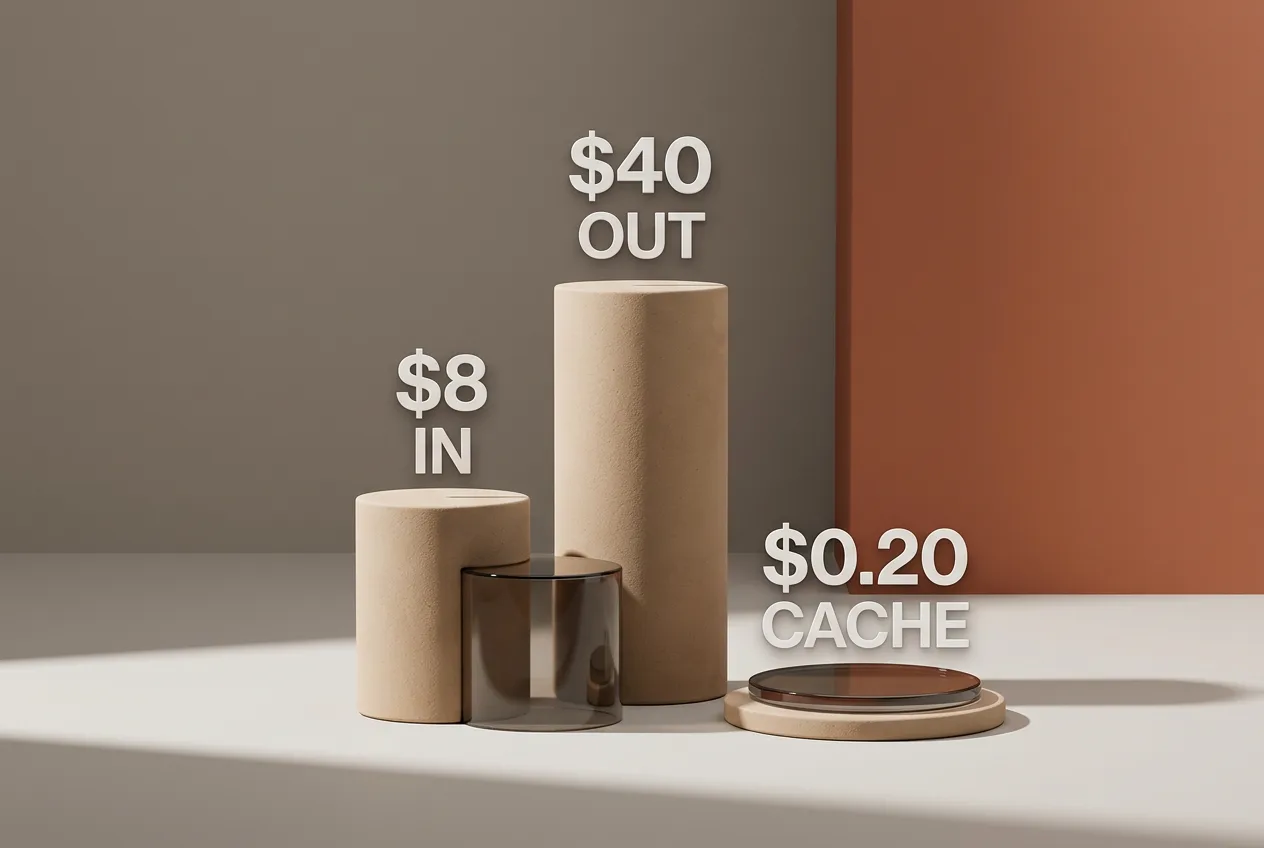
Pricing per million tokens is set at eight dollars for input and forty dollars for output. Cache reads cost twenty cents; five-minute and one-hour cache writes cost ten and sixteen dollars respectively. Batch API usage receives a fifty percent discount. An optional fast mode doubles output speed at sixteen dollars input and eighty dollars output. These rates sit twice as high as Opus 5.5 per token, yet cost per completed task can be comparable on demanding agentic workloads.
| Model | Input / Output per 1M tokens | Context Window | FrontierCode 2.0 Score |
|---|---|---|---|
| Claude Fable 5.2 | $8 / $40 | 1M | 49.1% |
| Opus 5.5 | $4 / $20 | 200K | 45.5% |
| GPT-6 Astra | $5 / $25 | 1M | 42.8% |
Interface access mirrors other Claude models and requires no additional technical setup beyond plan selection. Security measures include stronger cyber and biology safeguards than the previous version, reducing unnecessary blocks. Independent index scores place Fable 5.2 ahead of Opus 5.5 on aggregate intelligence metrics. Real-world coding tests sometimes favor Opus 5.5 on cost-to-accuracy balance for shorter tasks.
Reported limitations center on the doubled per-token cost relative to Opus 5.5 and the requirement for paid plans. Outputs average thirty percent faster than Fable 5.1. No retirement date has been announced before November 2027. Public user reviews remain limited in the first days after launch; early tester notes highlight clearer communication and faster iteration on large code migrations.
Frequently asked questions
What is the context window size of Claude Fable 5.2?
The model provides a 1M-token context window and supports a maximum of 128K output tokens. This specification appears in Anthropic’s official model documentation released on launch day.
How much does Claude Fable 5.2 cost per million tokens?
Standard pricing is eight dollars for input and forty dollars for output. Cache reads are twenty cents per million tokens and batch API usage receives a fifty percent discount.
Is Claude Fable 5.2 available on the free plan?
No. Access is restricted to paid Claude plans including Pro, Max, Ultra, Team, and Enterprise. The model picker shows it only after a qualifying subscription is active.
How does Claude Fable 5.2 compare with Opus 5.5 on coding benchmarks?
Fable 5.2 scores 49.1 percent on FrontierCode 2.0 versus 45.5 percent for Opus 5.5. It also leads on FrontierSWE v2 and several computer-use benchmarks, though per-token cost is double.
Filed under
Comments 9