Reviews Mistral
Mistral Voxtral 3 Review: Speech-to-Text, TTS and Voice Agent SDK Pricing and Performance
At a glance
Mistral released Voxtral 3 on October 20, 2026, with three STT variants, one TTS model and a LiveKit-based voice agent SDK. This review examines performance numbers, API rates and deployment choices.
Mistral Voxtral 3 review examines the family of speech models and the LiveKit-based SDK that Mistral AI launched on October 20, 2026. The release combines batch and realtime speech-to-text, text-to-speech and a single pipeline for voice agents that call tools and generate responses. Developers can test the models through the Mistral API or request on-premise licenses.
Mistral Voxtral 3 Review of Models and Performance
The STT lineup includes Voxtral Small Transcribe 3 for high-accuracy batch work with speaker diarization and context biasing, Voxtral Mini Transcribe 3 at 4 billion parameters for faster cheaper batch jobs, and Voxtral Mini Transcribe Realtime 3 for streaming with end-of-turn detection. The single TTS model, Voxtral Mini TTS 3, supports emotion, pace and emphasis control through implicit cues or explicit tags and offers Pro Voice cloning from roughly 30 minutes of audio. The SDK routes audio through STT, an LLM such as Mistral Small 4 for reasoning and tool calls, then back to TTS in one stream.
Batch STT supports more than 50 languages including all 24 official EU languages, while realtime STT and TTS each cover around 35 languages plus 50 dialects for TTS. On FLEURS 45, Small Transcribe 3 reports 4.1 percent WER when language is forced and 4.0 percent when inferred, well below Whisper large-v3 figures of 16 percent and 14.9 percent. Diarization reaches 18.4 percent cpWER on public tests, ahead of Pyannote at roughly 19 percent, and keyphrase recall hits 94.6 percent with context biasing. Realtime latency stays under 500 milliseconds with 6.4 percent WER at 480 milliseconds on FLEURS 35. Independent Artificial Analysis placed Small Transcribe 3 third overall at 2.1 percent AA-WER and Mini fifth at 2.2 percent, while the TTS model ranked around twelfth in voice arenas.
Self-hosted STT weights carry an Apache 2.0 license; TTS weights use a more restrictive commercial license. SIP telephony and WebRTC are supported out of the box, and EU and US API endpoints are live with additional global options through OpenRouter.
Voxtral 3 Pricing, Deployment and Comparison
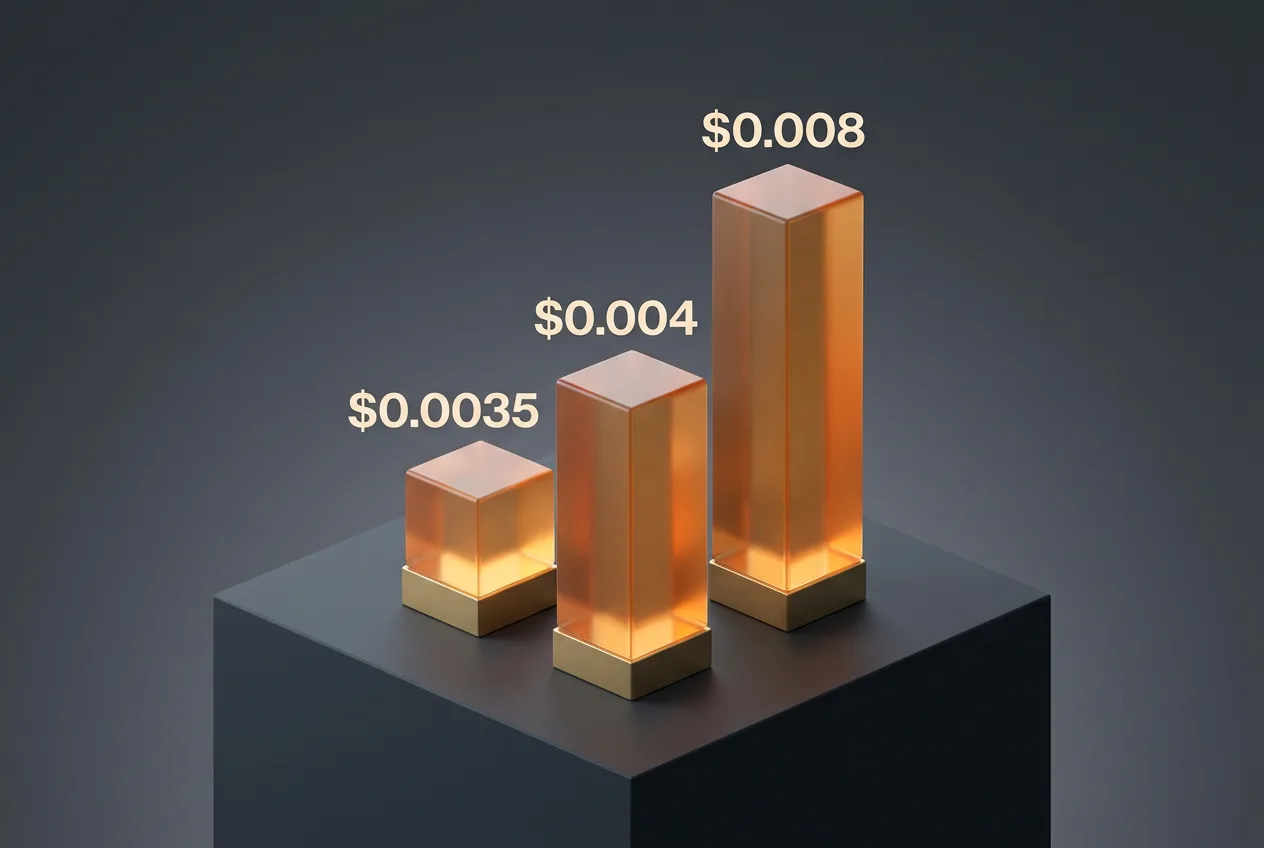
Public preview rates list batch Mini STT at $0.0035 per minute, Small STT at $0.004 per minute and realtime STT at $0.008 per minute. TTS costs $13 per million characters. A full voice agent pipeline using Mistral Small 4 runs at $0.04 per minute, while routes that call other LLMs cost $0.08 per minute. These figures sit at roughly half the published OpenAI Realtime API rate in comparable usage patterns.
Registration uses the existing Mistral API console with immediate access to playgrounds. No additional hardware details have been published for self-hosted deployments, and independent long-term agent evaluations remain limited because the release is still in preview. EU AI Act watermarking rules apply to all generated audio.
| Service | Realtime STT rate | Full agent rate | WER on FLEURS | Languages (realtime) |
|---|---|---|---|---|
| Voxtral 3 | $0.008/min | $0.04/min | 6.4% at 480 ms | 35+ |
| OpenAI Realtime | Higher | Higher | Not listed | English primary |
| Whisper large-v3 | Batch only | N/A | 14.9–16% | 99 total |
Common user comments on forums and review channels note strong diarization and low latency for contact-center style agents, while some testers report occasional drops in accent handling on low-resource languages. Complaints center on the preview status that leaves production SLAs undefined and on the restrictive TTS self-host license. No major security incidents have been reported for the new models.
Limitations and Current Standing of Voxtral 3
Public preview status means exact self-host hardware requirements, full production rollout timeline and comprehensive independent agent benchmarks are still pending. TTS licensing limits commercial self-hosting compared with the open STT weights. Watermarking obligations under the EU AI Act add compliance steps for generated speech. Context length and tool-calling depth depend on the paired LLM, so end-to-end agent performance varies with the chosen model.
Compared with earlier Mistral voice efforts, Voxtral 3 consolidates the full pipeline into one SDK and lowers per-minute costs. Relative to broader market options it improves reported WER on FLEURS and adds built-in diarization and voice cloning. Developers evaluating voice agents should test latency and accent coverage on their specific language mix before scaling.
Frequently asked questions
What languages does Voxtral 3 support?
Batch STT covers more than 50 languages. Realtime STT and TTS each handle around 35 languages with over 50 dialects available for TTS output.
How much does the Voxtral 3 voice agent API cost?
Full pipeline pricing starts at $0.04 per minute when paired with Mistral Small 4 and rises to $0.08 per minute with other LLMs. Separate STT and TTS rates apply for partial use.
Is Voxtral 3 available for self-hosting?
STT models carry an Apache 2.0 license and can be requested through Mistral sales. TTS weights use a more restrictive commercial license that limits self-host deployment options.
What latency does realtime transcription achieve?
Vendor tests show sub-500 millisecond latency with 6.4 percent WER at 480 milliseconds on FLEURS 35. Independent rankings place the models among the top five STT systems by accuracy.
Filed under
Comments 1